All projects
E-commerce · machine learning
Feature Engineering for Machine Learning
Amazon Retail
Building ML feature pipelines from a core data lake — with no warehouse, no data model and no dashboards.
Apache Spark Scala AWS EMR Amazon S3 Amazon Redshift Redshift Spectrum EC2 GPU
The team
- 1 Data Engineer
- 1 BI Engineer
- 3 ML Engineers
- 1 Software Development Engineer
- 1 Technical Product Manager
- 1 Senior Product Manager
Starting state
- Only a product idea and a set of requirements
Use cases
- Onsite attribution
- Customer perception based on survey data
Architecture
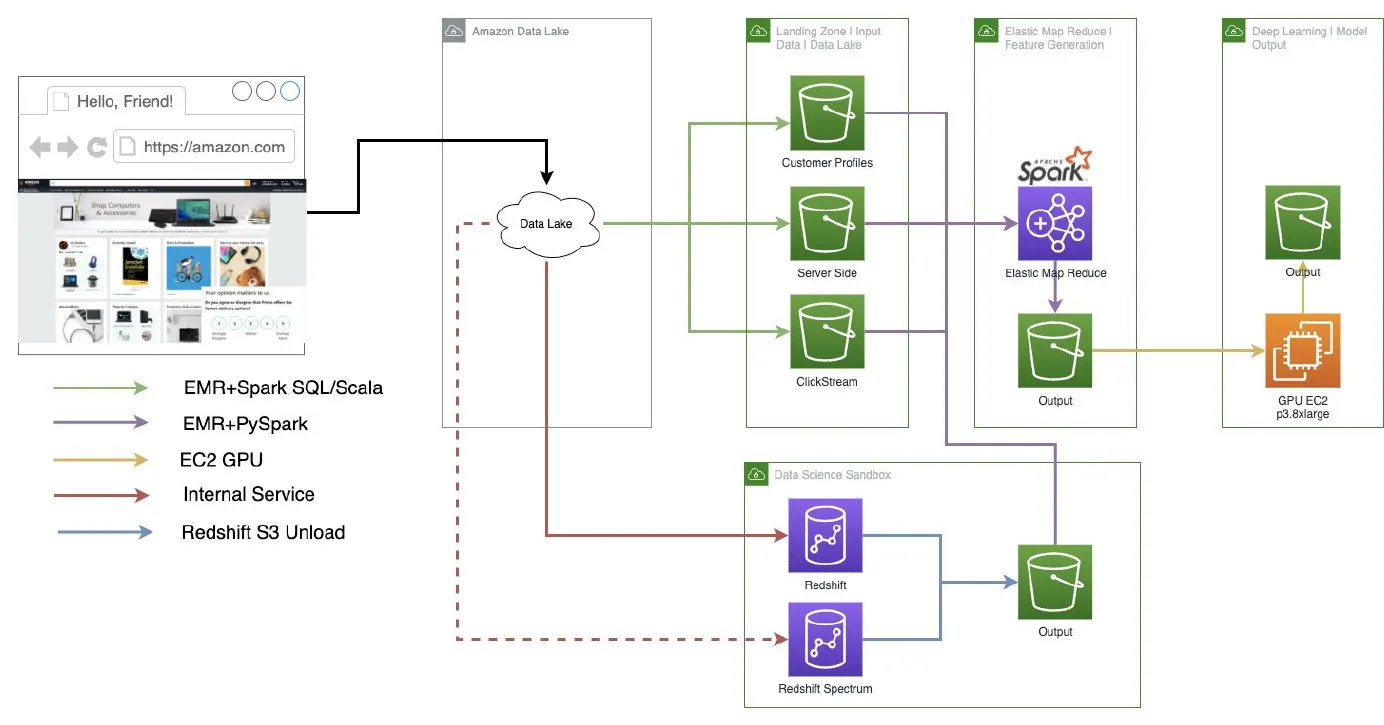
What was built
- Extract from the core data lake using in-house Spark and Scala into a project-owned S3 account
- EMR and Spark to combine the data into features
- Separate paths for EMR+Spark SQL/Scala, EMR+PySpark, EC2 GPU and Redshift S3 unload
- A data science sandbox on Redshift and Redshift Spectrum
What changed
- A pure ML data engineering project: no dimensional model, no warehouse and no BI layer, because none of them were needed.
- The data engineering work was preparing data, enforcing data quality, automating pipelines and automating the ML build so model freshness could be measured.
- Features were produced in a project-owned account, decoupling the ML team from the core lake's release cycle.
Let's talk about your data platform
Tell us what you are working on. We reply within one business day, and we will tell you plainly if we are not the right fit.
Other projects
E-commerce marketplace · 400 employees
Oracle Data Warehouse to AWS Redshift
AbeBooks (an Amazon subsidiary)
Migrating a marketplace off Oracle, PL/SQL and Crystal Reports onto Redshift and Tableau.
Amazon Redshift Matillion ETL Tableau AWS EMR
+4 more
Read the project
Consumer technology · internal data products Product Analytics for a Voice Assistant
Amazon Alexa — Natural Language Understanding
Replacing manual CSV extracts with an automated Redshift and Tableau product analytics stack.
Amazon Redshift Redshift Spectrum Tableau Amazon SageMaker
+1 more
Read the project
Video games · player analytics Delta Lake for Gaming Analytics
Microsoft Xbox — The Coalition
Moving a game studio off on-premise SQL Server and Hive onto an Azure Databricks lakehouse.
Azure Databricks Delta Lake Power BI Azure Data Factory
+3 more
Read the project