All projects
Telecommunications
Serverless Data Lake for a Telecom
One of the largest North American telecom companies
A config-driven AWS data lake where every job spins up its own EMR cluster and tears it down.
Amazon S3 AWS EMR Apache Spark AWS Athena Snowflake Tableau Alteryx Sphinx
The team
- 1 Data Engineer
- 2 BI Engineers
- 1 Front End Engineer
- 3 Architects
- 6 ETL / big data developers
- 1 Big Data Manager
Use cases
- Ingesting data into a Snowflake staging layer
- Transforming raw data in the S3 data lake
- ML pipelines for data quality
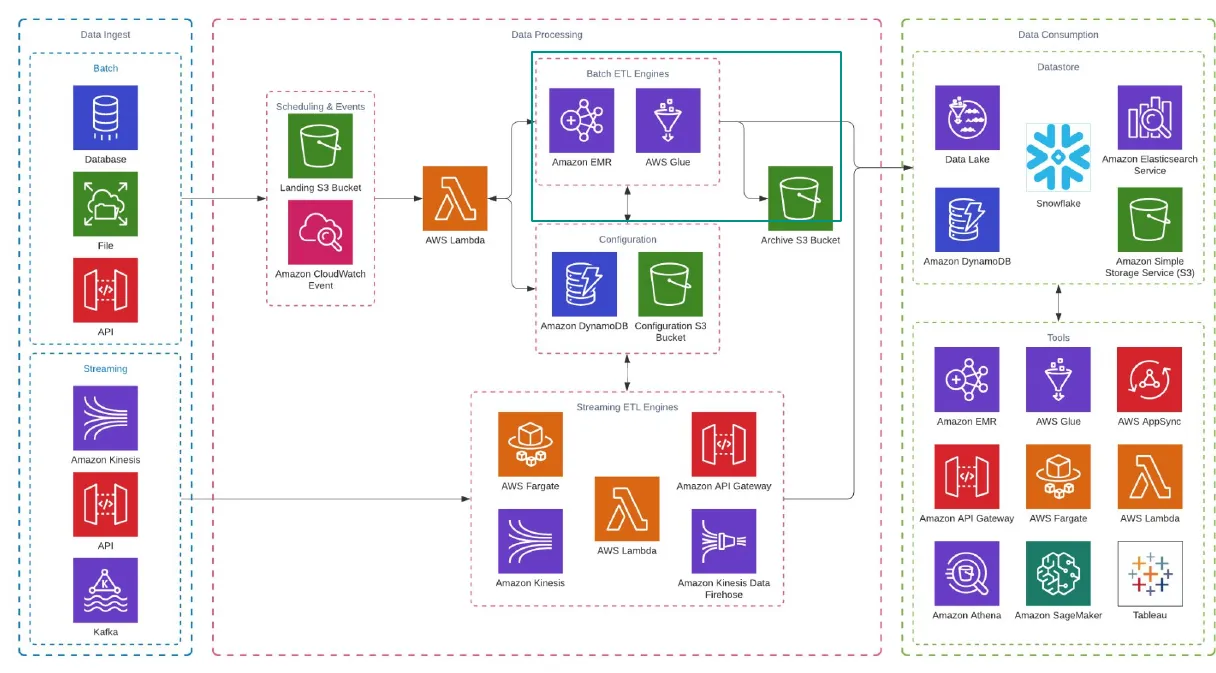
Architecture
What was built
- EMR and Spark jobs triggered by file volume rather than a fixed schedule
- Each job defined as a set of YAML configuration files in a Git repo
- Jobs create their own EMR cluster and terminate it on success
- Athena for SQL over the processed data on S3
- Selected jobs pushing data into Snowflake
- Tableau and Alteryx for consumption
- Sphinx for documentation and a data quality portal
What changed
- Compute cost tracked actual work, because clusters existed only for the length of a job.
- Volume-based triggers meant pipelines reacted to data arriving instead of waiting for the next window.
- Pipelines were configuration, not bespoke code, so a new feed did not mean a new codebase.
- The team's direction was consolidating onto Snowflake and moving to EMR Serverless.
Let's talk about your data platform
Tell us what you are working on. We reply within one business day, and we will tell you plainly if we are not the right fit.
Other projects
E-commerce marketplace · 400 employees
Oracle Data Warehouse to AWS Redshift
AbeBooks (an Amazon subsidiary)
Migrating a marketplace off Oracle, PL/SQL and Crystal Reports onto Redshift and Tableau.
Amazon Redshift Matillion ETL Tableau AWS EMR
+4 more
Read the project
Consumer technology · internal data products Product Analytics for a Voice Assistant
Amazon Alexa — Natural Language Understanding
Replacing manual CSV extracts with an automated Redshift and Tableau product analytics stack.
Amazon Redshift Redshift Spectrum Tableau Amazon SageMaker
+1 more
Read the project
E-commerce · machine learning Feature Engineering for Machine Learning
Amazon Retail
Building ML feature pipelines from a core data lake — with no warehouse, no data model and no dashboards.
Apache Spark Scala AWS EMR Amazon S3
+3 more
Read the project